


1.0 Executive Summary: The AML Data Matching Challenge
AML data matching compares customer and organization records with internal data, watchlists or other authorized reference sources to identify possible identity relationships. Effective matching combines data profiling, standardization, exact and fuzzy techniques, supporting attributes, calibrated thresholds and human review. It can improve the data supplied to AML screening workflows and reduce unnecessary candidate matches, but it does not replace screening, transaction monitoring, case management or compliance decisions.
Poorly standardized names, aliases, transliteration differences, missing identifiers and records distributed across multiple systems can affect screening results. Strict matching may overlook relevant variations, while overly permissive matching may create excessive false positives for investigators to review.
A reliable workflow must therefore improve the underlying customer data, compare multiple identity attributes and make uncertain results explainable. This whitepaper examines the data-matching techniques, controls and implementation steps that support more reliable AML screening.

The price of compliance failures is skyrocketing: global AML and KYC enforcement fines have now crossed the $30 billion milestone.
2.0 Where Data Matching Fits Within an AML Program
AML programs rely on several distinct capabilities, including customer identification, sanctions and watchlist screening, transaction monitoring, investigation and regulatory reporting. Data matching supports these processes by improving the customer and organization records supplied to them. It is not a substitute for the screening lists, monitoring rules, case-management systems or decisions managed by compliance teams.
Customer Onboarding and KYC
During onboarding, matching can determine whether a new applicant may already exist in a customer database under a different name, address or identifier. Connecting possible duplicate records helps teams avoid creating fragmented customer profiles and provides more complete data for identity verification and customer due diligence.
The effectiveness of these checks depends heavily on the quality of the customer data used throughout KYC.
Sanctions and Watchlist Screening
Before customer records are compared with an authorized sanctions, politically exposed person or other watchlist source, names and supporting attributes should be standardized. Matching techniques can then identify exact and approximate similarities for further evaluation.
A candidate match does not confirm that a customer is the listed person or organization. Dates of birth, addresses, nationalities, registration details and other available attributes must be considered within the institution’s screening and review procedures.

While more recent global crackdowns have yielded multi-billion-dollar penalties, PayPal’s historic $7.7 million OFAC settlement highlights how stringently regulators monitor automated payment systems for trade sanction gaps involving nations like Iran and Cuba.
Customer-Data Remediation
Existing databases often contain duplicate, incomplete or conflicting customer records. Profiling, cleansing, deduplication and entity resolution can reveal these problems and connect records that may represent the same customer or organization.
Remediation can create a more consistent customer view for periodic reviews and rescreening, while preserving source information needed to understand how records were resolved.
Cross-System Identity Resolution
Customer information may be distributed across onboarding, account, payment, CRM and legacy platforms. Entity resolution helps determine which records across these systems may refer to the same person or organization, even when they do not share one dependable identifier.
The resulting relationships can provide more complete customer context to downstream AML systems. However, identity resolution should remain explainable: teams need access to the compared values, applied rules, source records and confidence evidence behind each potential relationship.
3.0 Why Poor Customer Data Affects AML Screening
Screening results depend on the completeness, consistency and accuracy of the records being compared. A sophisticated matching engine cannot fully compensate for customer data that is missing, incorrectly structured or disconnected across systems.
Inconsistent Names and Formats
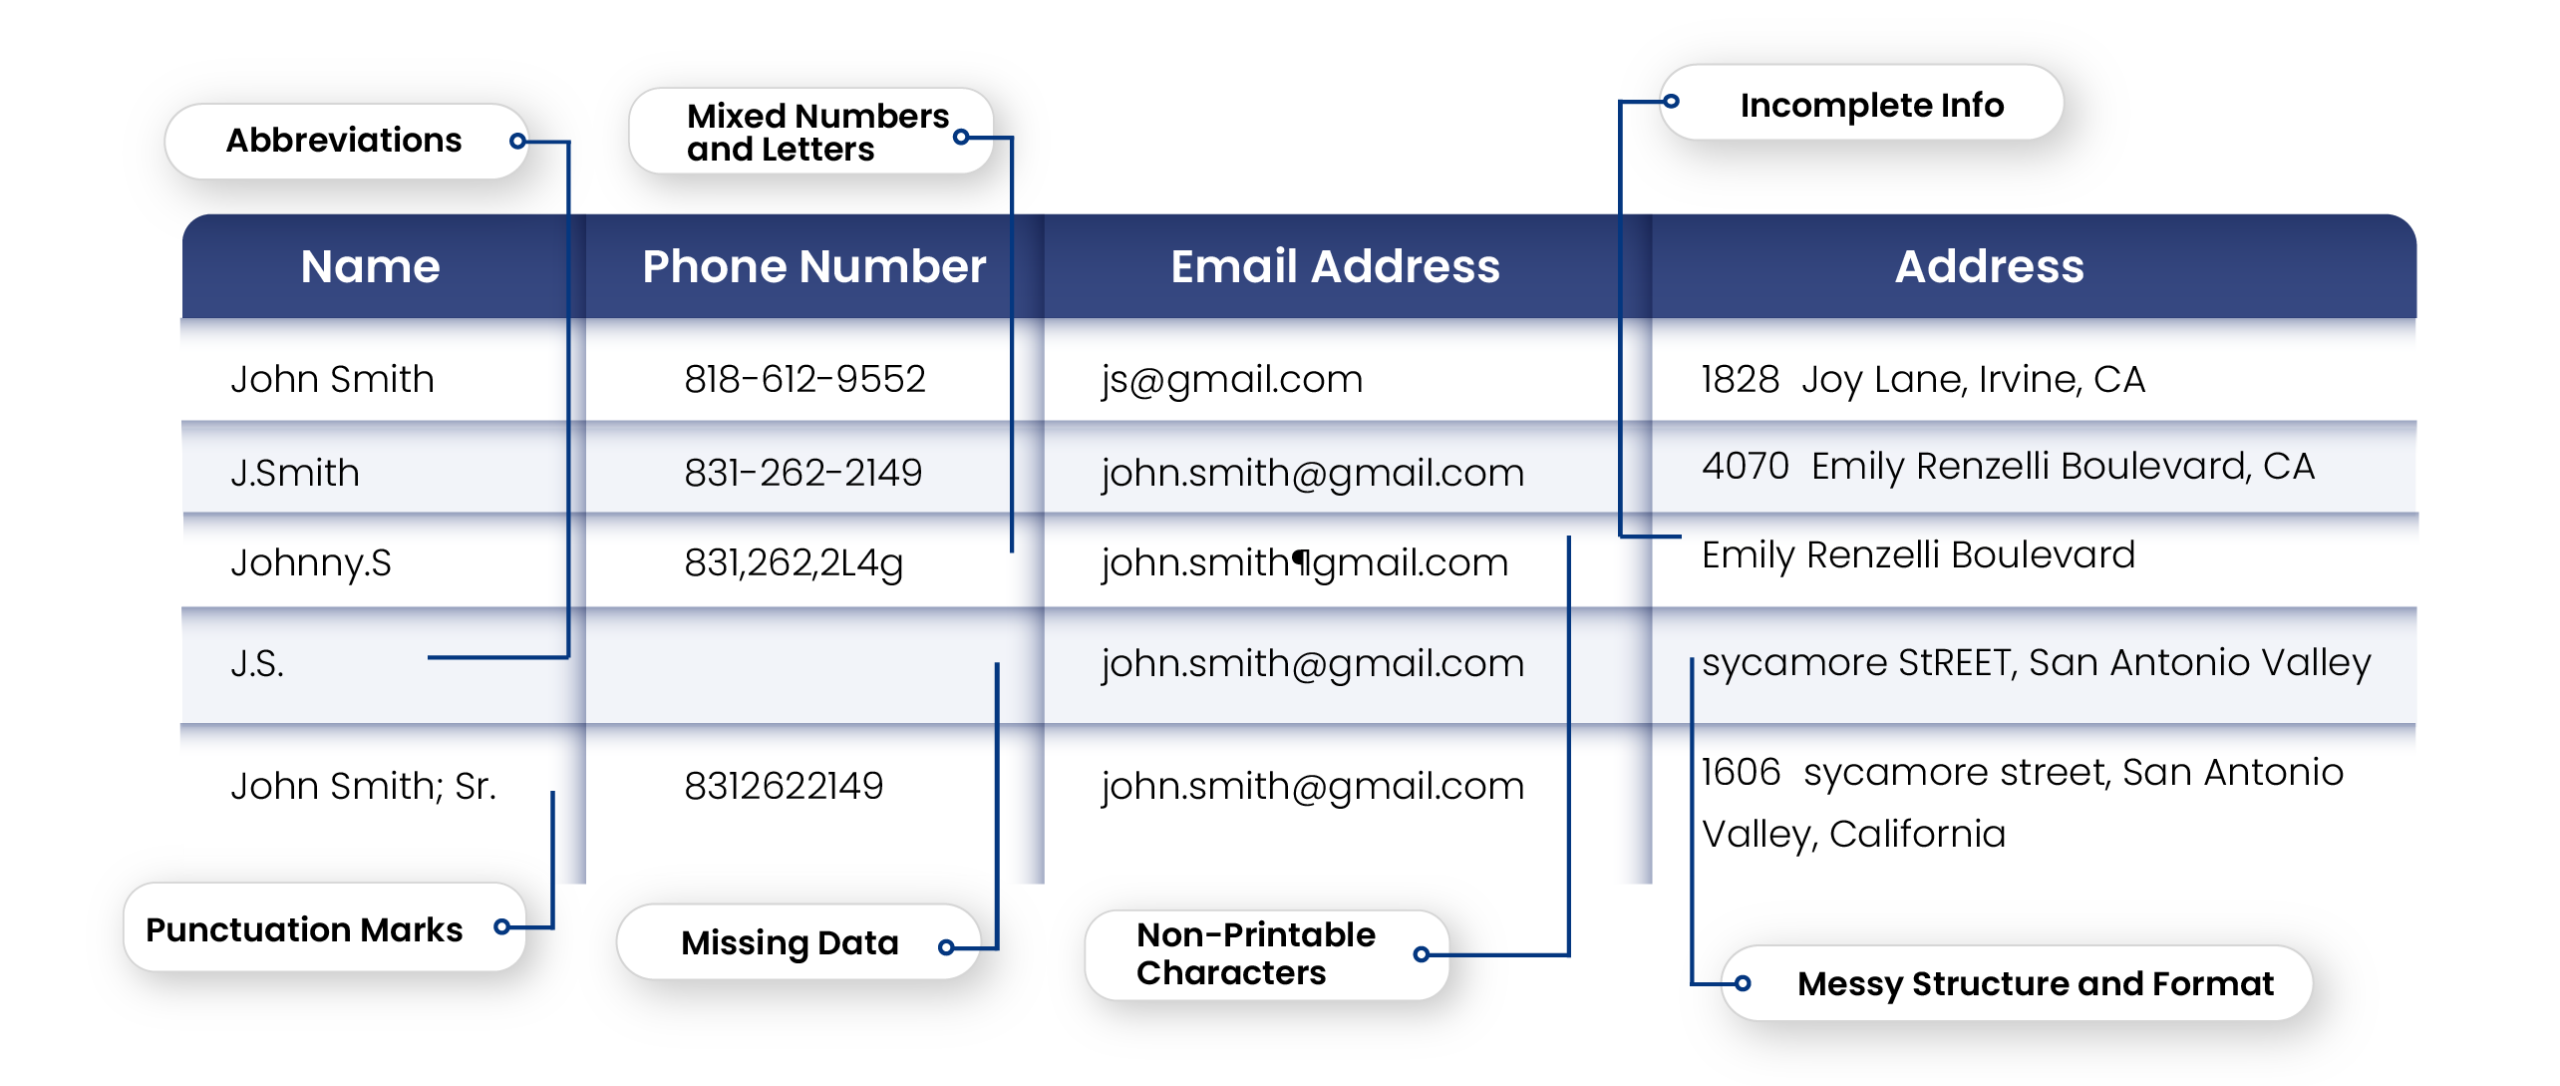
The same customer name may be stored with different spelling, punctuation, capitalization, abbreviations or component order. Organization names may also contain inconsistent legal suffixes or trading names. Without standardization, these variations can create unnecessary candidate matches or prevent related records from being found.

Duplicate and Fragmented Records
One customer may have separate records across business units, products or legacy platforms. If those records are screened independently, investigators may receive duplicate alerts or work with an incomplete view of the customer. Data deduplication and entity resolution can help connect these fragments before or alongside screening.
Incorrectly Structured Data
Names, addresses and identifiers may be stored in the wrong fields, combined into one field or represented differently by each source system. These structural inconsistencies can prevent matching rules from comparing equivalent information.
Multilingual and Transliteration Variations
Names written in different scripts can produce several valid Latin-character spellings. A single rigid transliteration rule may overlook relevant variations, while broad comparison rules may generate too many weak candidates.

Limited Data Lineage
When teams cannot identify where a value originated or how it was transformed, it becomes harder to investigate a match and defend the resulting decision. Screening workflows should preserve the original values, standardized values and source-system references.
Data profiling should be performed before configuring matching rules. It helps teams identify missing values, inconsistent formats, unusual patterns and source-specific problems that may affect screening quality.
4.0 Common AML Name and Entity Matching Challenges
AML data matching must account for legitimate variations in how people and organizations are represented. These variations can arise through data entry, language conversion, source-system limitations or changes to customer information.

Misspellings and Typographical Errors
Inserted, omitted, transposed or substituted characters can prevent exact matching. For example, “Johnathan” may appear as “Jonathan,” while a business name may contain a minor error introduced during manual entry.
Aliases, Nicknames and Previous Names
Individuals may use shortened names, known aliases, maiden names or former legal names. Organizations may operate under trading names or previously registered names. These relationships should be evaluated with additional identity attributes rather than accepted solely because an alias is similar.
Transliteration and Multiple Scripts
Names converted from Arabic, Cyrillic, Chinese or other writing systems may have several valid Latin-script representations. For example, “Muhammad,” “Mohammed” and “Mohamad” may reflect transliteration choices rather than separate identities.
Reordered or Missing Name Components
Given names, middle names, family names and prefixes may appear in different orders across systems. Some sources may omit a middle name, shorten a compound surname or store the complete name in a single field.
Phonetic Variations
Different spellings may have similar pronunciations. Phonetic matching can identify some of these variations, but its effectiveness depends on the language and naming convention being evaluated.
Common Names and Shared Attributes
A high name-similarity score provides weak evidence when a name is widely shared. People may also share addresses, dates of birth or family contact information. Matching logic must consider the combined strength and reliability of the available attributes.
Organization Names and Legal Suffixes
Business records may contain abbreviations, translated names, legal suffixes, subsidiaries or variations in punctuation. “ABC Holdings Limited” and “ABC Holdings Ltd.” may be related, while similarly named companies can remain separate legal entities.
Incomplete and Conflicting Records
A customer record may contain an incomplete name, outdated address or conflicting identifier. Matching systems should account for missing values without interpreting the absence of information as positive evidence.
These challenges require more than exact character comparison. Effective AML data matching combines normalization, multiple matching techniques, supporting attributes and review controls to identify relevant candidates without treating every similarity as a confirmed identity.
5.0 AML Name- and Entity-Matching Techniques
AML data matching generally combines multiple techniques. Each method addresses a different type of variation, and no single technique provides sufficient evidence for every customer, organization or dataset.
| Matching technique | What it compares | Where it helps | Important limitation |
| Exact matching | Identical values after basic normalization | Dependable identifiers and consistently formatted records | Misses spelling, transliteration and formatting variations |
| Fuzzy matching | Character-level similarity between values | Misspellings, omitted characters and minor data-entry differences | Broad thresholds can generate unrelated candidates |
| Phonetic matching | Similarity in how names sound | Differently spelled names with similar pronunciation | Performance varies by language and naming convention |
| Token-based matching | Individual words or name components regardless of order | Reordered personal names and organization names | Common tokens can create weak similarities |
| Alias and reference matching | Known nicknames, former names, trading names and aliases | Recognized alternative identities | An alias relationship does not independently confirm identity |
| Transliteration-aware matching | Variations created when names move between writing systems | Multilingual customer and reference data | One name can have several valid transliterations |
| Numeric and identifier matching | Exact or controlled comparison of dates and identifiers | Dates of birth, registration numbers and customer identifiers | Incorrect or shared identifiers can mislead the decision |
| Multi-attribute matching | Combined evidence across names and supporting fields | Distinguishing genuine relationships from coincidental name similarity | Requires appropriate weighting and sufficiently complete data |
Fuzzy matching is particularly useful when exact values are unavailable, but it should not operate in isolation. A name similarity score becomes more meaningful when evaluated alongside dates of birth, addresses, nationalities, registration details or other relevant attributes.
Matching rules can assign different weights to each field and place results into match, review or non-match ranges. The configuration should reflect the quality of the source data, the languages represented and the consequences of false-positive and false-negative decisions.
Integration of Data from Over 500 Sources: Because financial firms have multitudes of disparate data sources, they will need integration abilities to connect those sources onto one platform. DME allows for the integration of over 500 data sources with no additional third-party plugins or connectors (unless required or requested).

Whether your organization is struggling with poor customer data quality, or with data spread across disparate sources, our solution can help you improve and build more efficient, effective, and sustainable processes; enabling your firm to meet AML regulations better, and faster.

6.0 A Practical AML Data Matching Workflow
An AML data-matching workflow should be repeatable, explainable and separate data preparation from final screening or compliance decisions.
Step 1: Define the Matching Objective
Establish whether the workflow is intended to find duplicate customers, prepare data for watchlist screening, connect records across systems or remediate an existing customer database. The objective determines which data sources, attributes and error tolerances are appropriate.
Step 2: Profile the Source Data
Measure missing values, duplicate rates, field formats, unusual patterns and source-specific inconsistencies. Profiling reveals whether important attributes such as names, dates of birth, addresses or registration numbers contain enough usable information for matching.

Step 3: Standardize Comparable Values
Normalize capitalization, punctuation, whitespace, name components, dates, addresses and organization suffixes. Preserve the original values alongside standardized versions so reviewers can trace every transformation.
Step 4: Generate Candidate Records
Use exact rules, blocking criteria or other filters to identify plausible comparisons without evaluating every record against every other record. Candidate generation should improve processing efficiency without excluding important variations prematurely.
Step 5: Compare Multiple Attributes
Apply exact, fuzzy, phonetic, token-based or transliteration-aware techniques to the relevant fields. Combine name similarity with supporting evidence from dates of birth, addresses, identifiers and other available attributes.
Step 6: Score and Classify Results
Use documented rules, weights and thresholds to separate strong candidates, uncertain cases and unlikely matches. A high score should indicate the combined strength of the available evidence rather than a confirmed compliance decision.
Step 7: Review Uncertain Candidates
Provide reviewers with the source values, standardized values, field-level scores and applied rules. Review decisions should be recorded so teams can evaluate recurring issues and refine the configuration.
Step 8: Deliver Results to Downstream Systems
Approved and reviewed results can be exported or supplied through an API to authorized screening, case-management, customer-data or analytics systems. The output should retain source identifiers and decision evidence.
Step 9: Monitor and Recalibrate
Evaluate match quality, review volume and source-data changes over time. Thresholds and rules may need adjustment when new systems, customer populations, languages or reference sources are introduced.

Almost 50% of Companies Have Been Victims of Financial Crime.
7.0 How to Reduce False Positives Without Overlooking Relevant Candidates
A false positive occurs when unrelated records are presented as a possible match. A false negative occurs when a relevant identity relationship is not identified. Tightening a threshold may reduce false positives while increasing false negatives, so both outcomes must be evaluated together.
Improve Data Before Adjusting Thresholds
Repeated false positives may originate from incomplete, duplicated or poorly standardized customer records rather than the similarity algorithm itself. Profile and clean the source data before compensating with stricter thresholds.
Treat Names as One Part of the Evidence
A similar name should generate a candidate for evaluation, not establish identity by itself. Supporting attributes such as date of birth, address, nationality, registration number or other available identifiers can strengthen or weaken the candidate.
Use Field-Level Rules and Weights
Attributes should contribute according to their reliability. A dependable identifier may carry more weight than a common surname, while missing information should not automatically count as confirming or conflicting evidence.
Account for Common Values
Frequently occurring names, addresses and organization terms provide less distinguishing evidence. Matching rules can account for value frequency and require stronger supporting attributes when common values are involved.
Establish Separate Decision Ranges
Use distinct ranges for likely matches, likely non-matches and uncertain candidates requiring review. This prevents borderline results from being automatically accepted or rejected.
Use Conflicting Evidence
A strong name similarity may be weakened by substantially different dates of birth, locations or identifiers. Document how conflicting attributes affect the score instead of considering only positive similarities.
Make Candidate Matches Explainable
Reviewers should be able to see which fields matched, the technique used, each field’s contribution and the original source values. Explainability helps reviewers resolve cases consistently and identify rules that require recalibration.
Test with Representative Labelled Records
Evaluate the configuration using records whose correct relationships are already known and that reflect actual languages, name patterns, source systems and data-quality problems. Measure precision, recall, false-positive rate, false-negative rate and review volume rather than relying on a single overall accuracy percentage.
The appropriate balance depends on the workflow and the institution’s documented requirements. Data-matching software can help teams apply and test these controls, but the organization remains responsible for determining acceptable thresholds and review procedures.
8.0 How to Evaluate AML Data Matching Quality
AML data matching quality should be evaluated using a representative labelled dataset in which the correct identity relationships are already known. A single accuracy percentage is insufficient because it can hide important differences between unnecessary candidates and overlooked relationships.
| Measure | What it shows |
| Precision | The proportion of predicted matches that are correct |
| Recall | The proportion of genuine relationships successfully identified |
| False-positive rate | How often unrelated records are presented as candidates |
| False-negative rate | How often genuine relationships are overlooked |
| Review rate | The proportion of results requiring human evaluation |
| Processing time | Whether the workflow completes within operational requirements |
| Explanation coverage | Whether users can understand and trace each candidate decision |
Testing should include exact matches, difficult genuine matches, common names, multilingual records, transliteration variations, missing attributes and similar records that belong to different entities. It should also represent every important source system and customer population.
Teams should test more than one threshold configuration. Results can then be compared to determine how changes affect precision, recall and review workload. The selected configuration should be documented along with the dataset, rules, thresholds, product version and approval process.
Match quality and processing performance should be reported separately. A configuration may process records quickly while generating too many uncertain candidates, or produce strong results at a review volume that is operationally impractical.
9.0 How DataMatch Enterprise Support AML Data Workflow
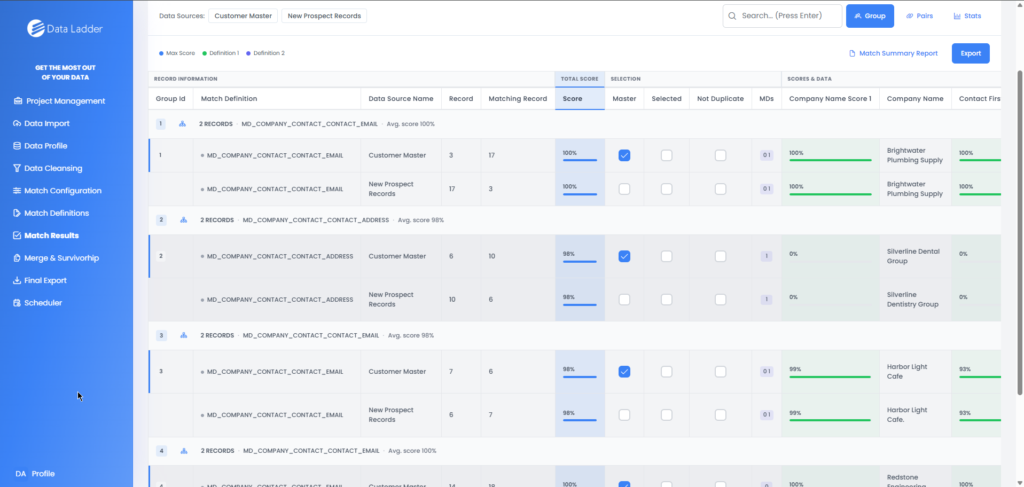
DataMatch Enterprise helps organizations prepare, compare, resolve and consolidate customer and organization records used within AML workflows. It provides a data-quality and entity-resolution layer that can operate before or alongside authorized screening and case-management systems.
Profile and Prepare Customer Data
Teams can profile source datasets to identify missing values, inconsistent formats, duplicates and unusual patterns. Cleansing and standardization rules can then normalize names, addresses, dates, organization suffixes and other attributes before matching.
Configure Multiple Matching Techniques
DataMatch Enterprise supports exact, fuzzy, phonetic, token-based and other configurable matching methods. Teams can compare multiple fields, assign rules or weights and adjust thresholds according to their data and review requirements.
Inspect and Review Match Evidence
Users can examine compared records, field-level similarities and match results before approving consolidation decisions. Keeping the original and standardized values available helps reviewers understand why a candidate relationship was identified.
Resolve Duplicate and Fragmented Identities
Records from onboarding, CRM, account and legacy systems can be matched to identify possible duplicate or related customer profiles. Survivorship rules can determine which values are retained when approved records are consolidated.
Integrate Matching into Existing Workflows
The browser-based platform provides a visual interface for configuring and reviewing matching projects. Its REST API supports integration with downstream applications and repeatable data pipelines.
Deploy Within the Required Environment
DataMatch Enterprise supports Docker-based Linux deployment across on-premises and cloud environments. Organizations can select an architecture consistent with their infrastructure, security and governance requirements.
Data Ladder has also published the methodology and configuration behind its 10-million-record DataMatch Enterprise benchmark so technical evaluators can review the scope and conditions of the performance test.
DataMatch Enterprise does not supply sanctions or politically exposed person lists, monitor transactions, determine customer risk, manage regulatory investigations or make AML compliance decisions. These functions remain with the organization’s authorized data providers, screening platforms and compliance teams.
10.0 AML Data Matching Implementation Checklist
Before deploying or changing an AML data-matching workflow, confirm the following:
Scope and Data
- Define whether the objective is customer deduplication, cross-system identity resolution, screening-data preparation or customer-data remediation.
- Identify the source systems, reference datasets and downstream applications involved.
- Confirm which personal and organization attributes are available, permitted and sufficiently complete for matching.
- Profile each source for missing values, duplicate records, inconsistent formats and language variations.
Matching Configuration
- Select techniques appropriate for exact values, spelling differences, phonetic variations, aliases, reordered components and transliteration.
- Combine names with supporting attributes rather than treating name similarity as confirmation.
- Document field-level rules, weights, blocking criteria and conflicting evidence.
- Establish separate thresholds for likely matches, uncertain candidates and likely non-matches.
Testing and Review
- Create a representative labelled test set containing both genuine and difficult non-matches.
- Measure precision, recall, false positives, false negatives and human-review volume.
- Confirm that reviewers can inspect source values, standardized values, match scores and applied rules.
- Record reviewer decisions and define an escalation process for unresolved cases.
Integration and Governance
- Determine whether the workflow requires batch processing, an API or both.
- Preserve source identifiers, transformation history and decision evidence.
- Confirm deployment, access-control, security and data-retention requirements.
- Assign ownership for approving rules, thresholds and production changes.
Ongoing Monitoring
- Reassess matching performance when data sources, customer populations or reference data change.
- Monitor review volumes and recurring false-positive patterns.
- Retest configurations after software, algorithm or rule changes.
- Maintain versioned documentation of datasets, configurations, results and approvals.
Conclusion
AML screening depends on the quality and consistency of the customer and organization records being evaluated. Misspellings, aliases, transliteration differences, missing attributes and fragmented identities can create unnecessary candidate matches or prevent relevant relationships from being identified.
A reliable data-matching workflow profiles and standardizes source data, combines multiple matching techniques, evaluates supporting attributes and separates clear results from cases requiring review. Its effectiveness should be measured using representative labelled data, documented thresholds and operational metrics such as precision, recall and review volume.
DataMatch Enterprise supports this data layer through profiling, cleansing, configurable matching, deduplication, entity resolution and survivorship capabilities. It can integrate with existing workflows through batch processes or a REST API, but it does not replace watchlist providers, transaction-monitoring systems, case-management platforms or compliance decisions.
Request a DataMatch Enterprise demo to evaluate the platform using representative data, matching requirements and deployment constraints.
Frequently Asked Questions About AML Data Matching
What is AML data matching?
AML data matching compares customer or organization records with internal data, watchlists or other authorized reference sources to identify possible identity relationships. It may use exact, fuzzy, phonetic, token-based and multi-attribute matching techniques.
Is AML data matching the same as AML screening?
No. Data matching identifies similarities and possible relationships between records. AML screening applies an organization’s authorized lists, risk rules and review procedures. Matching can support screening, but it does not independently determine whether a person or organization presents a compliance risk.
How does data quality affect AML screening?
Missing attributes, inconsistent formats, duplicate records and spelling or transliteration variations can generate unnecessary candidate matches or cause relevant relationships to be overlooked. Profiling and standardization make records more consistent before comparison.
How can organizations reduce AML false positives?
Organizations can improve source-data quality, compare multiple identity attributes, account for common values, configure field-level rules and use separate thresholds for matches, non-matches and review cases. Configurations should be tested using representative labelled data.
Is fuzzy name matching sufficient for AML workflows?
No. Fuzzy matching can identify spelling and character variations, but name similarity alone does not confirm identity. It should be combined with exact, phonetic, token-based or transliteration-aware techniques and supporting attributes such as dates of birth, addresses or identifiers.
Is DataMatch Enterprise a complete AML compliance platform?
No. DataMatch Enterprise provides profiling, standardization, matching, deduplication and entity-resolution capabilities that can support AML data workflows. It does not provide watchlist data, transaction monitoring, risk scoring, case management or compliance decisions.