


Last Updated on October 14, 2026
Entity resolution is the process of identifying, linking, and consolidating records that refer to the same real-world entity across disparate data sources, even when those records are inconsistent, incomplete, or formatted differently. It’s also one of the most underestimated dependencies in enterprise data work. Get ER wrong and every downstream process from MDM and customer analytics all the way to fraud detection inherits the problem.
This guide covers how entity resolution works in practice, where it consistently breaks down at scale, and what to look for when evaluating ER software for a large-scale data environment.
What is Entity Resolution?
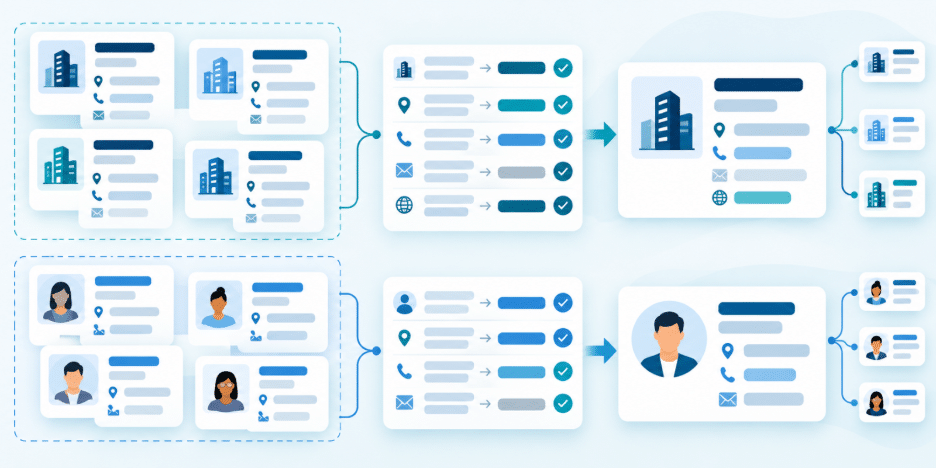
Entity resolution is the process of determining which records across one or more data sources refer to the same real-world person, organization, product, location, or other entity. It compares identifying attributes, evaluates the strength of possible matches, and groups related records even when the data is incomplete, inconsistent, or stored without a common identifier.
For example, a CRM may contain a customer named “Maria Hernandez,” while a billing system records the same person as “M. Hernández.” Their names are not identical, but similarities across their address, email, telephone number, and other attributes may provide enough evidence to link the records to the same customer.
Entity resolution usually involves more than finding identical duplicates. It can:
- Link records across different systems and datasets.
- Distinguish similar records that belong to different entities.
- Group multiple records into a single entity cluster.
- Identify uncertain matches that require human review.
- Create a consolidated or canonical record for downstream use.
Deduplication is often one step within entity resolution. Deduplication generally identifies duplicate records within a dataset, whereas entity resolution can connect related records across multiple sources and determine which records collectively represent the same real-world entity.
Entity resolution uses data matching techniques to compare attributes and estimate whether records belong to the same entity. Deduplication, record linkage, fuzzy matching, clustering, and merge/purge may support different stages of this broader process, but they are not interchangeable terms.
What Is an Entity Resolution Framework?
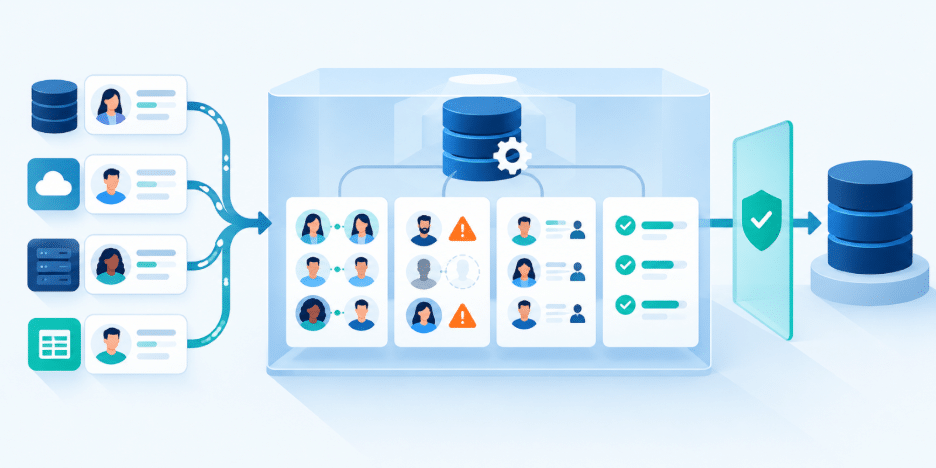
An entity resolution framework is the end-to-end process used to identify which records refer to the same real-world entity. It defines how data is prepared, how potential matches are generated and evaluated, how related records are grouped, and how uncertain decisions are reviewed and monitored.
A complete enterprise entity resolution framework generally includes the following stages:
1. Data Ingestion and Schema Alignment
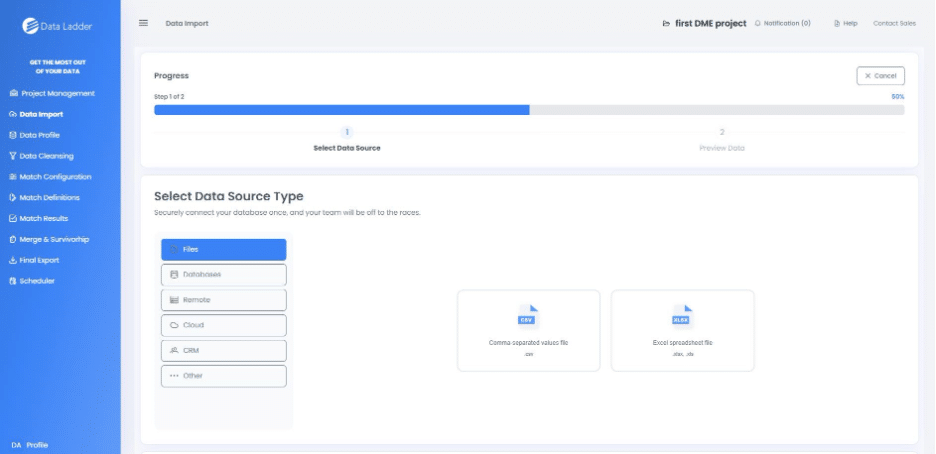
Records are collected from systems such as CRMs, ERPs, databases, cloud applications, spreadsheets, and third-party data sources. Because these sources often use different field names, formats, and schemas, equivalent attributes must be mapped before meaningful comparisons can begin.
For example, one system may use “Customer Name,” another “Account Holder,” and a third separate the same information into first-name and last-name fields.
2. Data Profiling and Standardization
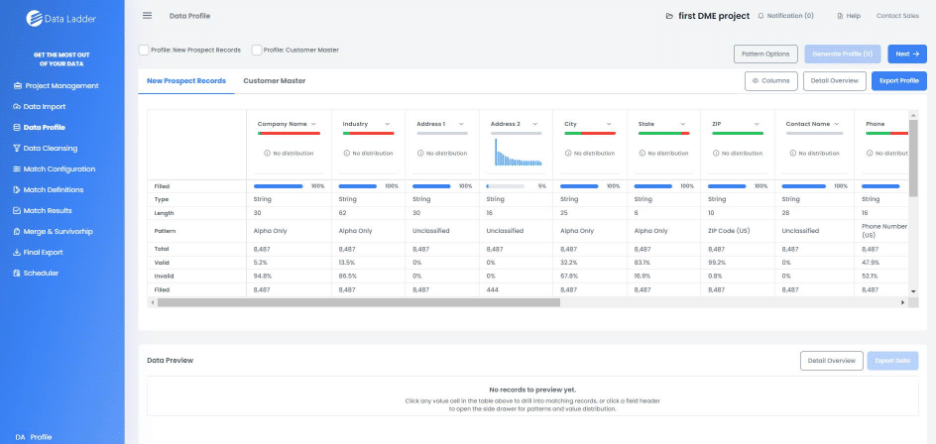
The data is examined for missing values, invalid formats, inconsistent casing, extra characters, abbreviations, and other quality problems that could affect matching.
Standardization converts comparable values into consistent formats. Names, telephone numbers, dates, addresses, company suffixes, and other identifying attributes may each require different preparation rules.
3. Blocking and Candidate Generation
Comparing every record with every other record becomes inefficient as data volume increases. Blocking narrows the search by identifying records that share selected characteristics and are therefore reasonable match candidates.
Blocking criteria may use attributes such as postal region, name tokens, telephone prefixes, email domains, or combinations of fields. Blocking improves processing efficiency, but overly restrictive rules can exclude genuine matches.
4. Attribute Comparison
Candidate records are compared across relevant attributes. Different fields may require different comparison methods.
Exact comparison may work for reliable account identifiers, while fuzzy or phonetic comparison may be more appropriate for names. Addresses, telephone numbers, dates, and organization names may require their own normalization and comparison logic.
5. Match Scoring and Classification
The evidence from each attribute is combined to determine the likelihood that two records belong to the same entity. Attributes can be weighted differently according to their reliability and importance.
Thresholds then classify candidate pairs as:
- Matches that can be accepted automatically
- Non-matches that should remain separate
- Possible matches that require human review
The appropriate thresholds depend on the consequences of false positives and false negatives for the use case.
6. Entity Clustering
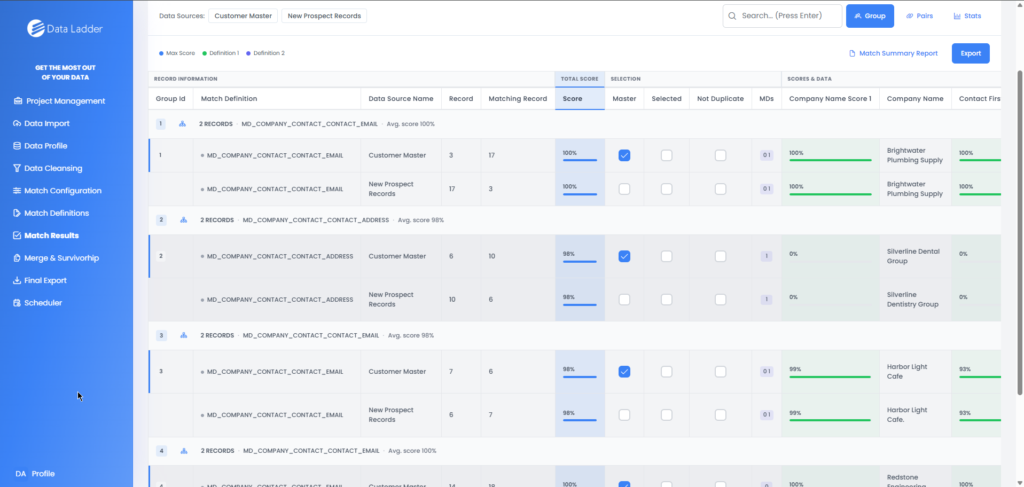
Pairwise match decisions are grouped into entity clusters. Each cluster represents the records believed to refer to one real-world entity.
Clustering requires careful control because an incorrect connection can cause unrelated records to be grouped through a chain of otherwise plausible matches.
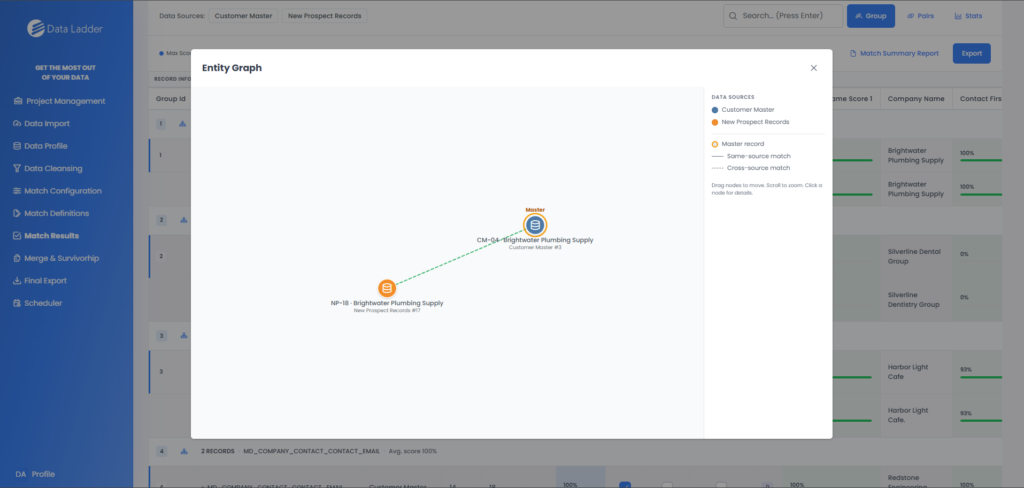
7. Canonicalization and Golden-Record Creation
After related records have been grouped, survivorship rules determine which values should represent the resolved entity. These rules may prioritize trusted source systems, the most recent value, the most complete value, or another business-defined standard.
The resulting canonical or golden record provides a consolidated view while maintaining links to the contributing source records.
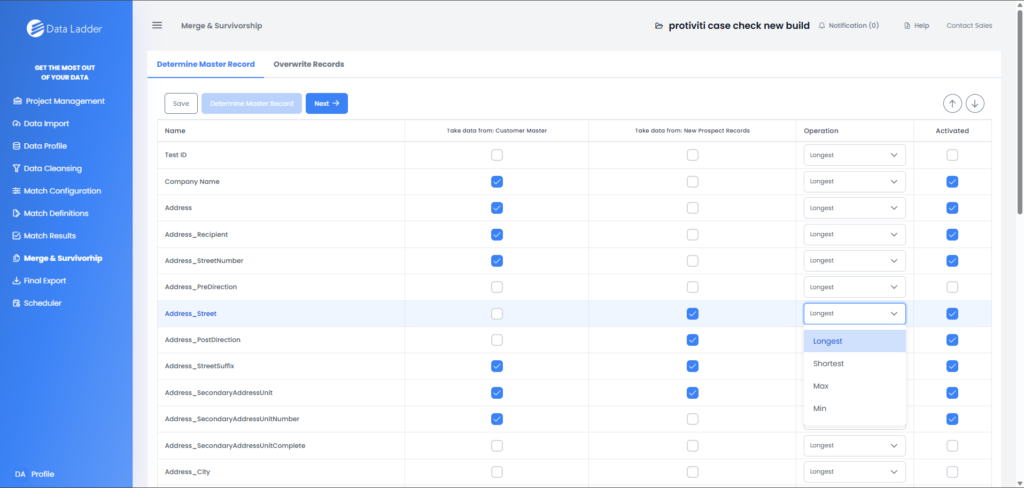
8. Human Review, Delivery, and Monitoring
Ambiguous matches should be routed to reviewers with the evidence needed to accept, reject, or investigate the proposed relationship. Resolved records can then be exported or delivered to downstream CRM, ERP, MDM, analytics, compliance, or operational systems.
Entity resolution is not necessarily a one-time activity. Data sources, record patterns, and business requirements change, so teams should monitor match quality, review volumes, false positives, false negatives, and changes in system performance over time.
Entity Resolution Techniques Compared
Entity resolution can use several techniques to determine whether records belong to the same real-world entity. These techniques are not mutually exclusive. Most enterprise workflows combine exact rules, similarity algorithms, weighted scoring, and human review based on the structure and quality of the available data.
| Technique | How it works and where it fits | Main limitation |
| Exact matching | Compares fields for identical values. It works well for standardized records containing reliable identifiers such as account numbers or verified email addresses. | Misses matches when values contain spelling, formatting, or data-entry differences. |
| Rule-based matching | Applies predefined conditions, such as matching when the name and address agree or when the email and telephone number agree. It provides transparent, business-controlled decisions. | Rules require ongoing maintenance and may not account for unfamiliar data variations. |
| Fuzzy matching | Measures the similarity between values rather than requiring exact agreement. It is useful for misspellings, abbreviations, transposed characters, and formatting differences. | Poorly selected algorithms or thresholds can produce false positives and false negatives. |
| Phonetic matching | Compares how words—particularly names—sound rather than how they are spelled. It can identify variations caused by pronunciation or transliteration. | Different people can have phonetically similar names, so additional attributes are usually required. |
| Probabilistic matching | Assigns weights to agreements and disagreements across multiple attributes to estimate whether records refer to the same entity. It is useful when no single reliable identifier is available. | The weights and thresholds must be calibrated and evaluated against representative data. |
| Machine-learning matching | Learns match patterns from labelled record pairs or reviewer feedback. It can adapt to complex datasets where manually defined rules are insufficient. | It requires suitable training data, monitoring, and a process for handling model drift. |
| Graph or collective matching | Uses relationships between records and entities alongside attribute similarity. It is useful when connections between people, organizations, accounts, transactions, or devices provide important evidence. | Implementation and evaluation are more complex than attribute-based matching alone. |
| Hybrid matching | Combines several techniques—for example, exact rules for reliable identifiers, fuzzy comparison for names, and probabilistic scoring across the complete record. | Greater flexibility also creates more configuration, testing, and governance requirements. |
The right approach depends on the entity type, data quality, available identifiers, acceptable error rates, and the consequences of an incorrect decision. Exact or deterministic methods may be sufficient for clean data with dependable identifiers, while inconsistent and incomplete enterprise data generally requires a hybrid approach.
Regardless of technique, match quality should be evaluated using representative labelled records. Teams should examine precision, recall, false positives, false negatives, and the number of uncertain cases requiring human review rather than relying on a single vendor-provided accuracy percentage.
Worked Example: Resolving Customer Records Across Enterprise Systems
Consider a fictional organization with customer information distributed across three systems:
- CRM: Alpine Medical Group, 1250 North Clark Street, contact@alpinemedical.example
- Billing system: Alpine Medical Group LLC, 1250 N. Clark St., accounts@alpinemedical.example
- Support platform: Alpine Med. Group, 1250 North Clark Street Suite 400, support@alpinemedical.example
No single customer identifier is shared across all three systems, and the organization name, address, and email address differ between the records. An entity resolution framework could process them as follows:
Profile and Standardize the Records
The system standardizes organization suffixes, street abbreviations, punctuation, casing, and email domains. “LLC” may be stored separately from the core organization name, while “Street” and “St.” are converted to a consistent format.
Generate Candidate Matches
Blocking rules identify the records as possible matches because they share name tokens, a postal address, and the same email domain. This prevents the system from comparing them against every unrelated customer in the database.
Compare the Attributes
Different comparison techniques are applied to each field:
- Fuzzy matching evaluates “Alpine Medical Group” against “Alpine Med. Group.”
- Address matching compares the standardized street and suite information.
- Exact matching confirms that the email addresses use the same organization domain.
- Rule-based or probabilistic scoring combines the available evidence.
Score and Classify the Match
The system assigns greater weight to the shared address and email domain than to minor differences in the organization name. If the combined evidence exceeds the approved match threshold, the records are classified as belonging to the same organization. If the result falls into an uncertain range, it is sent for human review.
Create the Resolved Entity
The three records are grouped into one entity while retaining links to their original systems. Survivorship rules can then select the preferred organization name, address, and contact details for a canonical record.
The resolved entity can be delivered to downstream CRM, billing, analytics, MDM, or reporting systems. The source records should remain traceable, so reviewers can understand how the entity was assembled and correct the decision if new evidence becomes available.
This example illustrates why entity resolution is broader than simply deleting duplicate rows. The process evaluates evidence across systems, groups related records, preserves source lineage, and creates a usable representation of the underlying entity.
Challenges of Entity Resolution
Despite the many approaches and techniques available for entity resolution, it falls short on several fronts. These include:
1. ER Works Well Only If the Data Is Rich and Consistent
Match accuracy in any ER system is only as good as the data it operates on — and most enterprise datasets are neither rich nor consistent.
For example:
If you have ‘Mike Rogers’ in two databases, an exact match or simple record linking can easily identify that one of them is a duplicate record. This is called deterministic matching and it is quite straightforward.
However, when you’re dealing with similar records with inconsistencies, such as misspellings, abbreviations, or nicknames (e.g., ‘Mike Rogers in one database and ‘Michael Rogers’ in another), it becomes difficult to match them. This phenomenon is called probabilistic matching and it becomes even more challenging when unique identifiers (such as address, SSN, or birth date) are missing or inconsistent across datasets, making it nearly impossible to perform any kind of deterministic matching, especially when handling large volumes of data.
2. ER Algorithms Don’t Scale Well
Traditional entity resolution techniques often fail when applied to big data environments like financial, government, and healthcare industries, where records span terabytes of data.
The business rules required to make the algorithms work would have to account for far larger data to work consistently. For example, the blocking technique – used to limit mismatched pairs when finding duplicates – is dependent on the quality of the record fields. If you have fields containing errors, missing values, or variations, you can end up inserting data into the wrong blocks and face higher false negatives.
3. Manual Entity Resolution is Complex and Resource-Intensive
It is not uncommon for organizations dealing with large volumes of data to opt for handling entity resolution projects in-house. The rationale behind this decision is that they can make use of their existing technical resources (software engineers, consultants, database administrators) without having to purchase any of the entity resolution tools available in the market.
However, there are a few problems with this approach.
Firstly, entity resolution isn’t a subset of software development. Sure, there are publicly available algorithms and blocking techniques that might be useful. But in the grand scheme of things, the skills it requires are vastly different, as the user will have to:
- Combine disparate unstructured and structured data sources.
- Know about encoding variations, nicknames, and linguistic differences very well for accurate matching.
- Adapt ER rules for different business use cases (e.g., customer data deduplication vs. fraud detection).
- Ensure that different matching techniques complement each other for consistency and reliable results.
It’s quite unlikely for a person to tick all these boxes, and even if it is possible, you have the risk of them leaving the firm. If the person leading or managing an ER project leaves the company, it can bring the entire initiative to a halt.
4 Reasons Why Entity Resolution Tools Are Better
Entity resolution tools offer significant advantages over traditional manual or rule-based ER methods. These include:
1. Higher Match Accuracy
Dedicated entity resolution tools that have sophisticated fuzzy matching algorithms and entity resolving capabilities in place can give far better record linking and deduplication results than common ER algorithms.
Matching records across heterogeneous datasets (e.g., SQL and NoSQL databases, spreadsheets, PDFs) can be exceptionally difficult due to different types of entities, encoding, formatting, languages, and schemas. Converting all this different type of data into a pre-defined schema through schema-matching and data exchange is a risky process and can result in the loss of valuable information.
Moreover, accurate fuzzy matching may require data analysts to use multiple string-metrics, such as Levenshtein Distance, Jaro-Winkler, and Damerau-Levenshtein. Implementing these manually is resource-intensive.
Entity resolutions tools incorporate a wide range of matching algorithms. They can seamlessly link records and significantly improve match accuracy and consistency across datasets.
2. Reduced Time-To-First Result
In most cases, time is critical for ER projects, especially in the case of master data management (MDM) initiatives that require a single source of truth. However, manual entity resolution projects can take months. Considering that the information relating to an entity can quickly change within weeks, the slow pace of manual ER can pose serious data quality risks and lead to missed opportunities and poor decision-making.
Let’s say a B2B sales and marketing firm wants to run campaigns on its top-tier accounts, Ideally, it should confirm that its targeted prospects haven’t switched jobs, changed titles, or retired before wasting any marketing spend. A manual ER process taking 6+ months risk many records becoming outdated, obsolete, or inaccurate. Most entity resolution tools can reduce this time by 50%, while some even bring the time-to-first result down to mere 15 minutes.
3. Better Scalability
Entity resolution tools are designed to process large-scale datasets without compromising performance. They are far more adept at ingesting data from multiple sources and run record linkage, deduplication and cleansing tasks at much larger scales.
For example, a government institution performing ER to identify (and prevent) fraudulent tax filings would find manual ER approaches and algorithms severely restricting and overwhelming. The sheer volume of the data in government databases (they have millions, if not trillions, of records) and the complexity of blocking techniques would make the efforts futile.
Automated entity resolution tools, however, can streamline the process. They can not only import data from various sources, but also ensure the efficiency of the process remains intact across large data volumes.
4. Cost-Savings
Entity resolution tools, particularly for enterprise level applications, require a sizable investment. For this reason alone, many data professionals tasked with ER may be reluctant to get them. They may feel that manual ER is more cost-effective and a better way to showcase their expertise (and improve their chances of promotion). However, the costs of project delays, poor matching accuracy, and labor resources often end up exceeding the investment in an automated ER tool.
ER tools allow data professionals to focus on high-value tasks, rather than spending months on manual matching. By reducing data errors, enhancing operational efficiency, and improving decision-making, automated ER solutions provide better financial outcomes in the long run.
Entity Resolution Use Cases
Entity resolution is used when an organization needs to determine whether records from the same or different systems represent one real-world person, organization, product or other entity. The appropriate attributes, matching techniques, thresholds and review controls depend on the operational decision the resolved data will support.
Customer 360
Customer information is often distributed across CRM, billing, support, e-commerce and marketing platforms. Entity resolution links records containing variations in names, contact details and account identifiers, helping organizations create a more complete customer view for service, analytics and personalization.
CRM Deduplication
Separate web forms, event lists, imports and sales tools can create multiple CRM records for the same lead, contact or account. Entity resolution identifies these duplicates even when values are incomplete or inconsistent, helping reduce duplicated outreach and improve reporting and account management.
Patient Identity Matching
Patient records may be distributed across electronic health records, laboratories, pharmacies, insurers and scheduling systems. Entity resolution compares names, addresses, dates of birth, contact details and available identifiers to support more complete longitudinal records and safer record retrieval. Because incorrect links can be harmful, patient-matching workflows generally require conservative thresholds and strong review controls.
KYC and AML Screening
Customers and organizations may appear in onboarding, account, sanctions and watch-list data under aliases, transliterations or incomplete identifiers. Entity resolution can connect these variations to support identity verification, regulatory screening and compliance investigations while retaining evidence behind match decisions.
Fraud Investigation
Fraudulent activity may involve related people, businesses, accounts, applications, devices, transactions or claims that appear under inconsistent identities. Entity resolution helps investigators identify these connections and build a more complete view of potentially suspicious activity. Graph analysis may then be applied to explore relationships among the resolved entities.
Supplier and Vendor Mastering
The same supplier can be registered multiple times across ERP, procurement, accounts-payable systems and regional supplier portals. Entity resolution consolidates these records to support spend analysis, supplier onboarding, payment controls and a more consistent view of vendor relationships.
Product and Catalog Matching
Equivalent products may use different names, descriptions, units, category labels or manufacturer identifiers across supplier feeds, marketplaces and inventory systems. Entity resolution and product-matching techniques can connect these records, helping organizations maintain cleaner catalogs and produce more consistent pricing and inventory analysis.
Mergers and System Consolidation
Mergers, acquisitions and system-retirement projects frequently create overlapping customer, supplier and operational records. Entity resolution helps determine which records refer to the same entities, which values should be retained and which records require manual review before systems are combined.
Data Migration and MDM Preparation
Moving unresolved data into a new CRM, ERP or master data management platform can reproduce existing duplicates and conflicts in the target environment. Entity resolution before migration helps identify duplicate records, reconcile source differences and provide cleaner inputs for governance, survivorship and mastering processes.
Government Record Linkage
Government agencies may maintain separate licensing, benefits, tax, enforcement and public-service records without a shared identifier. Entity resolution can link person or organization records across departments to support service coordination, program analysis and authorized investigations, subject to applicable privacy, access and review requirements.
Entity resolution should be evaluated against the intended operational decision—not only the number of records matched. A customer-marketing workflow may tolerate a different balance between false positives and false negatives than patient identity, financial compliance or fraud investigation.
How to Measure Entity Resolution Quality
Entity resolution quality should be tested against representative records whose correct relationships are already known. The principal measures are precision, which shows how many predicted matches are correct, and recall, which shows how many genuine matches the system successfully finds. F1 score can provide a combined measure when both error types matter.
A single accuracy percentage can be misleading because most possible record pairs are non-matches. Evaluation should therefore include false positives, false negatives, the percentage of cases requiring human review and the quality of complete entity clusters—not only individual record pairs.
Test data should reflect production conditions, including missing values, conflicting attributes, common names, shared addresses, multilingual data and records from important source systems. Processing time and scalability should be measured separately from match quality because a fast system can still produce poor matches.
The acceptable balance depends on the use case. Marketing workflows may favor higher recall, while patient identity, financial compliance and other high-risk applications may use stricter thresholds to reduce false positives.
How to Choose the Right Entity Resolution Software
Many ER tools differ in features, scope and value. Selecting the right entity resolution software for your needs is critical to ensuring accurate record matching, deduplication, and data unification. Here are some key factors to consider when choosing an entity resolution tool for enterprise data project:
1. Support for Disparate Data Sources
Enterprise data is often stored in different formats and scattered across multiple platforms like Excel, databases, CRMs, web applications, and delimited text files. The right entity resolution software should seamlessly import data from all relevant sources for the specific use-case.
DataMatch Enterprise’s Import module allows you to source data in various formats as shown above, which ensures its compatibility with diverse enterprise environments.
2. Scalable Data Profiling and Cleansing
The right entity resolution software must also profile and clean the data before any deduplication and record linkage efforts. DataMatch Enterprise (DME), using pre-built patterns based on Regex expressions, can determine valid and invalid records, null values, distinct entries, leading and trailing spaces, duplicates, formatting issues, and other inconsistencies.
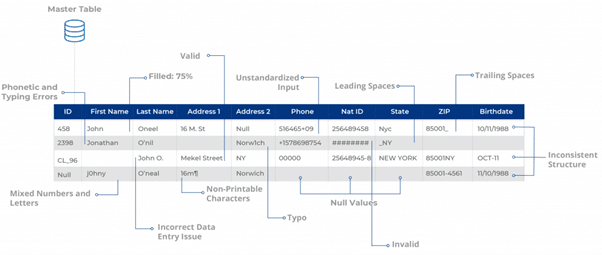
Once a profile is generated, the software should then provide data cleansing opportunities using various functionalities such as:
- Merging Fields – Consolidating multiple fields into one
- Removing Unwanted Characters – Cleaning up punctuation or extra spaces
- Replacing Characters – Standardizing inconsistencies in input data
- Removing Numbers – Stripping out non-essential numeric values
DataMatch Enterprise simplifies this process by using pre-built patterns based on Regex expressions to detect and cleanse invalid records at scale.

3. Advanced Matching Algorithms for Higher Accuracy
Many entity resolution tools claim to provide a high match score, but their effectiveness depends on how sophisticated the algorithms used to match records within and across multiple datasets are.
DataMatch Enterprise employs a range of advanced matching techniques (Exact, Fuzzy, Phonetic), and string-metrics algorithms to establish distance across entities and makes use of domain-specific libraries (nicknames, addresses, phone numbers) to provide a match accuracy rate that outperforms industry competitors.
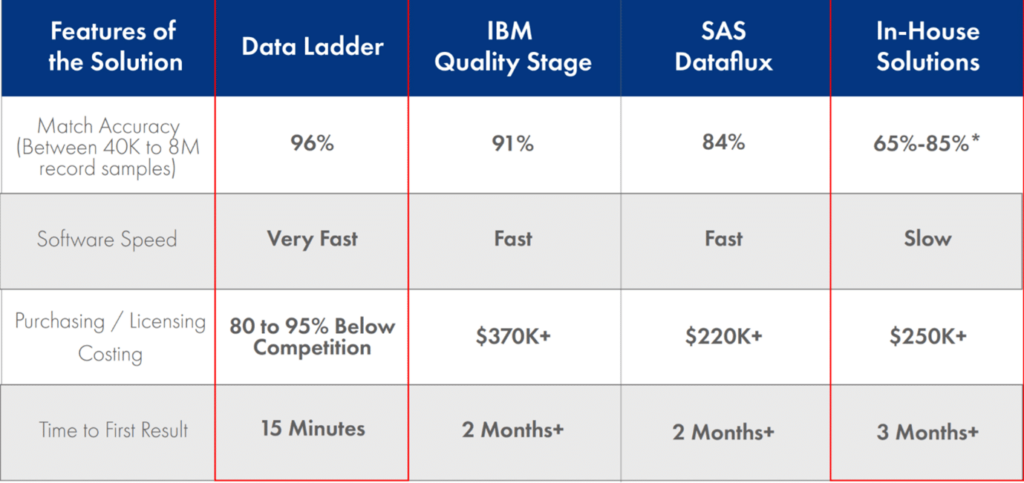
An independent study done by Curtin University found that DME’s match accuracy surpassed those of other vendors, including IBM’s Quality Stage and SAS Dataflux.
Blocking and scalability
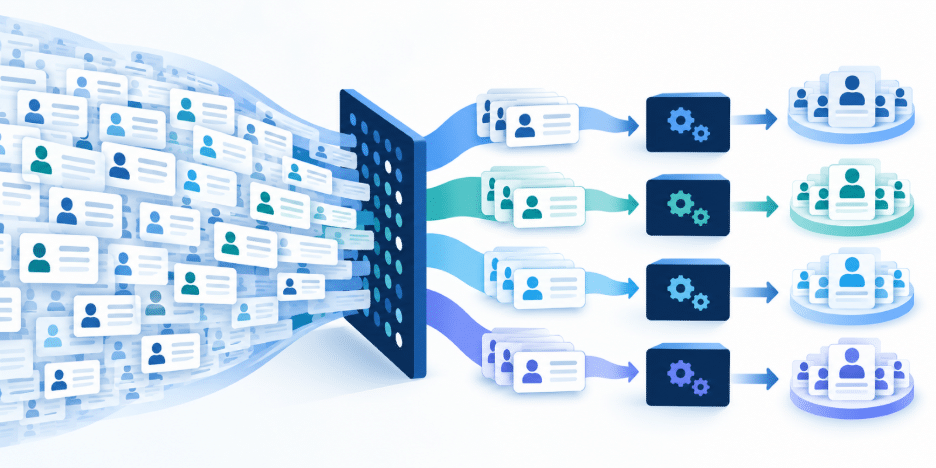
Blocking limits unnecessary comparisons by grouping records into smaller sets of likely matches. Evaluate whether the software supports multiple blocking strategies and can process your expected data volume without excluding genuine matches. Test both processing completion and match coverage as record volumes increase.
Precision, recall and threshold testing
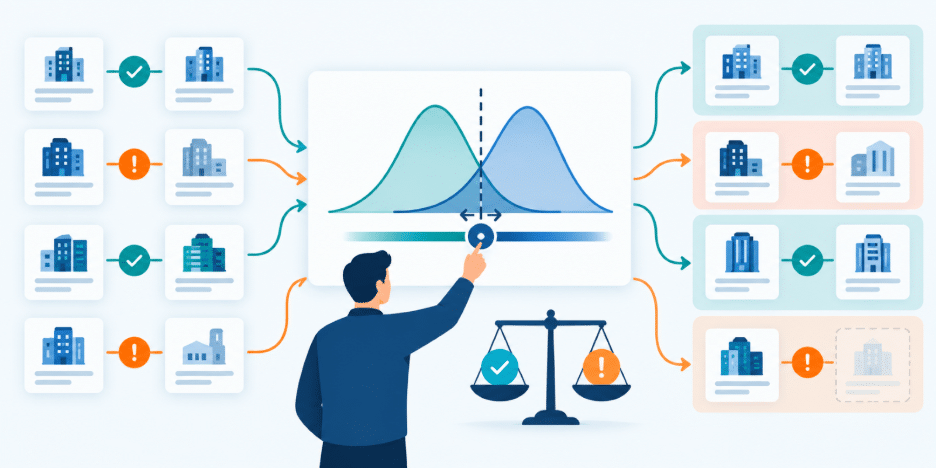
The software should let teams evaluate precision, recall, false positives, and false negatives at different match thresholds. Look for tools that make thresholds configurable and allow results to be tested against labelled records. A single overall accuracy percentage is not sufficient for understanding match quality.
Explainability and source lineage
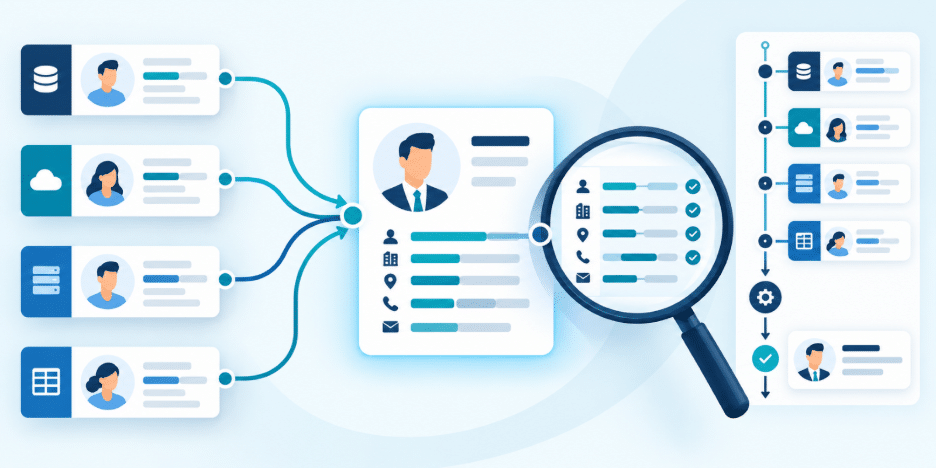
Reviewers should be able to understand why records were linked and which attributes contributed to the decision. The software should also preserve connections to the original source records. This traceability supports troubleshooting, auditing, governance, and correction of incorrect entity groupings.
Human-review workflow
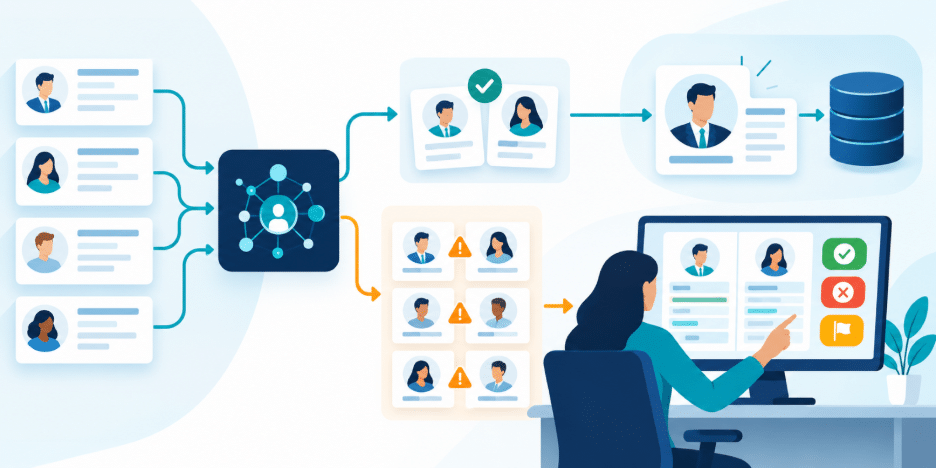
Uncertain matches should be routed to reviewers with the evidence required to accept, reject, or investigate them. Assess how the platform prioritizes review cases, presents record comparisons, records reviewer decisions, and feeds approved corrections back into matching rules or models.
Clustering and survivorship rules
Entity resolution extends beyond classifying individual record pairs. The software should group related records into controlled entity clusters and prevent weak connections from creating over-linked entities. Survivorship rules should determine which source values populate the canonical record while preserving source history and lineage.
API, batch and downstream integrations
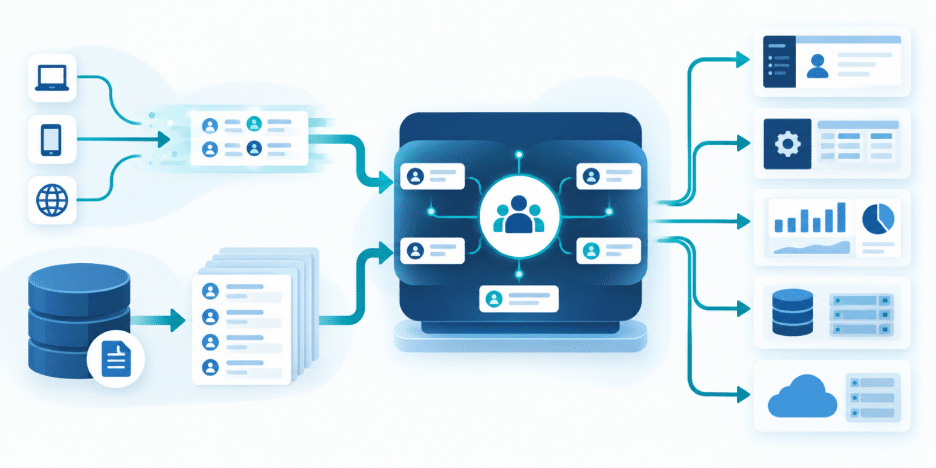
Consider how entity resolution will fit into existing data workflows. The platform may need to support scheduled batch processing, API-driven requests, file-based operations, or a combination of these approaches. Confirm that resolved records can be delivered to required CRM, ERP, MDM, warehouse, analytics, or operational systems.
Deployment, security and governance
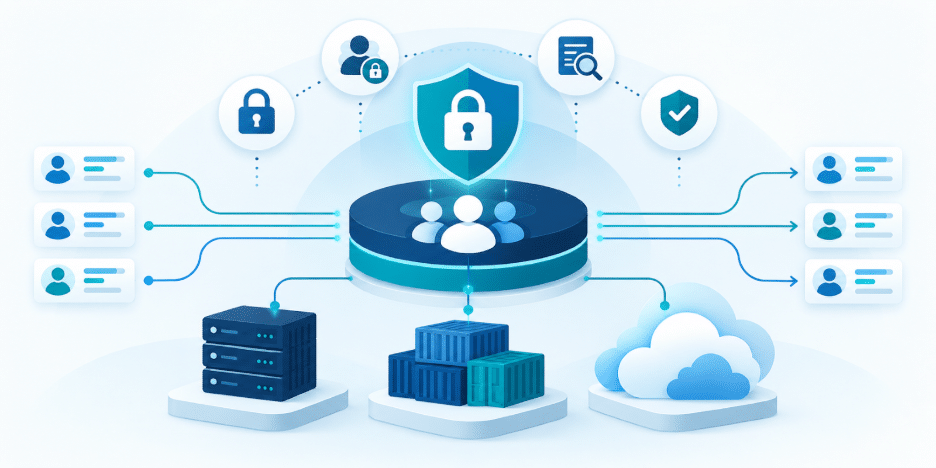
Evaluate whether the available deployment model fits your infrastructure and security requirements. Review hosting options, access controls, encryption, auditability, data retention, administrative permissions, and compliance responsibilities. Security claims should be confirmed through current technical documentation and organizational review.
Implementation and ongoing maintenance requirements
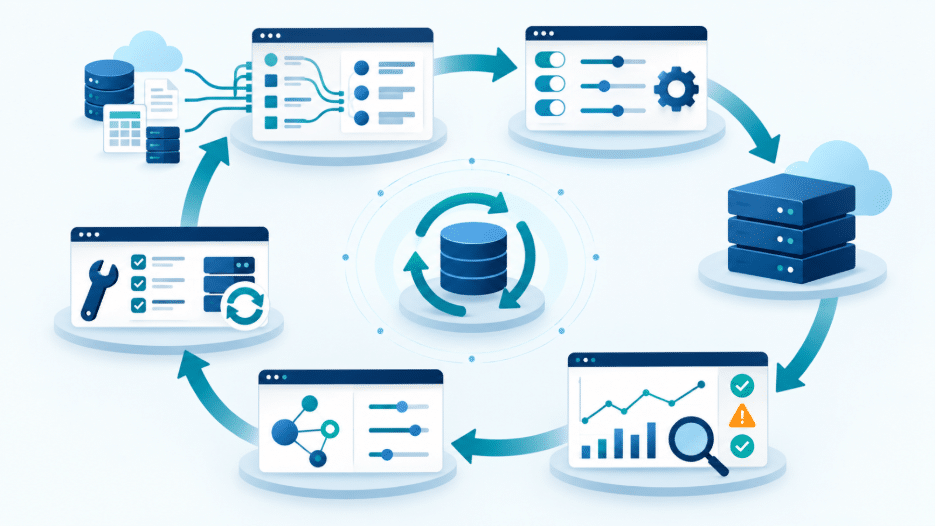
Entity resolution requires more than initial software installation. Compare the work needed for source mapping, data preparation, rule configuration, threshold testing, reviewer training, monitoring, and future updates. A flexible platform may require more technical ownership, while a highly automated tool may provide less control over match behavior.
Testing with representative customer data
Before selecting a platform, test it with records that reflect production conditions. Include missing attributes, difficult matches, similar non-matches, multilingual variations, common names, multiple source systems, and different entity types. Measure match quality, human-review volume, processing completion, elapsed time, and the effort required to configure and explain the results.
Visit our Best Entity Resolution Comparison, Entity Resolution solution page or contact our sales team to see how DataMatch Enterprise (DME) can improve your data strategy.
Frequently Asked Questions (FAQs)
Can entity resolution work without a unique identifier?
Yes. Entity resolution can compare combinations of attributes such as names, addresses, email addresses, telephone numbers, dates and organization details when no common identifier exists. The reliability of the decision depends on the quality, completeness and distinctiveness of the available attributes.
Does entity resolution require machine learning?
No. Entity resolution can use exact rules, fuzzy matching, phonetic algorithms, probabilistic scoring, machine learning or a hybrid approach. The appropriate techniques depend on the data, use case, available training examples and need for explainability.
Is entity resolution the same as identity resolution?
The terms overlap, but identity resolution usually focuses on people or customers across accounts, channels and devices. Entity resolution is broader and can apply to people, organizations, products, suppliers, locations, accounts and other real-world entities.
Does entity resolution always create a golden record?
No. Some implementations only identify and group records belonging to the same entity while preserving every source record. Creating a golden record is a separate canonicalization step that applies survivorship rules to select the preferred values for the resolved entity.
How often should entity resolution rules and thresholds be reviewed?
There is no universal schedule. Teams should review them when source systems, data formats, entity populations or business requirements change, and whenever monitoring shows unusual shifts in match rates, false positives, false negatives or human-review volumes.
What should an entity resolution proof of concept test?
A proof of concept should use representative records from the intended source systems. It should measure precision, recall, false positives, false negatives, cluster quality, review workload, processing completion and configuration effort. It should also test difficult matches, similar non-matches and missing or conflicting attributes.
When does entity resolution require human review?
Fully automated entity resolution handles the clear matches and clear non-matches with confidence. Human review becomes necessary for records that fall in a middle confidence band — close enough to flag as potential matches but not close enough to merge automatically. In high-stakes contexts (patient records, financial compliance, fraud investigation), organizations often set tighter thresholds and route more edge cases to human reviewers, even at the cost of throughput. The goal of ER tooling is to minimize that review queue while keeping false positives out of the resolved output.
How does DataMatch Enterprise handle data privacy and security during the entity resolution process?
Data privacy and security are critical in any data processing activity. DataMatch Enterprise adheres to industry-standard security protocols to ensure that your data is protected throughout the process. It offers features like data encryption to safeguard sensitive information, which also helps your organization comply with data protection regulations.